
Was my AI document matching solution in n8n too rigid?
September 7, 2026
This post continues from a series where I explore reliable data extraction from documents with AI. Did you miss the series? Don't worry, you can read it here!
Sometimes I get feedback on the posts I write and this makes writing them a lot more fun. Because what is the point of sharing your ideas and learnings if they would just disappear into a black void?
After the AI document matching series I got an e-mail from someone out of my network who liked the series a lot and followed along, but he also wondered if I hadn't been a bit too rigid in my n8n solution.
Too rigid, me? Never!
Remember that I used an AI agent for transforming markdown to a canonical object that is then cross referenced via a script? Well, his main concern was whether the script would still be a viable solution if the data to compare grew. Or would the script become unmanageable? It also fails if some fields don't match perfectly. In some real world cases fields use abbreviations or terms that mean the same things. Which means that the script should ultimately be extended with data mappings to deal with such things. And still that won't map fields with manual input data (yes in 2026 that is still a lot around). Quickly that small script could become a project on its own...
Slowly but surely, fuzzy requirements are creeping in...
He asked himself the following question: Would the agent be more suitable for cross referencing? So he built an alternative proof of concept with Claude Code. In essence he first created testcases using my blog posts and testfiles. Then he worked on alternative prompts for a Matching Agent and verified them with his test suite. He even added some extra checks that verified fuzzy differences in addresses (like the Dublin 8 vs Dublin examples we saw in the previous parts).
An LLM can do everything. But should I let it?
So the quick answer is ultimately yes. LLMs can do this too. But the answer to should I let it? is: it depends! as usual. There are always trade-offs that should be evaluated for the specific situation. In my example I gave in to the urge to keep the steps in between AI nodes as deterministic as possible so that I have structured data to work with. For this use case it might have seemed rigid but at the same time simple. Everything had to match exactly.
Summer came along and as usual for me projects wind down a bit. I decided to check out n8n's new academy material and thought about my feedback a bit more. It was cool to see someone read my posts and build something with it. So why not build on that idea with n8n?
I'm not going to summarise all the course info here, I recommend you check it out yourself, but there were some nuggets that stood out. Sometimes these supported my solution and other times I came to the conclusion that I could have used something else.
- The material explains when to go for an Agent node and when to use a simple AI node. Since my Extraction Agent did not need any tools or memory I could have better picked the AI node with less overhead. The extraction agent got demoted to a Basic LLM Chain node named Extraction prompt!
- I was very tempted to create a new Matching Agent after learning that you can plug anything* into one with n8n to finish more complex tasks. My idea was to give it tools to get the purchase order directly and use the former Healing Agent capabilities from part 3. But in the end I realised that this would add unnecessary overhead and I ended up swapping the AI agent for the Basic LLM Chain node named Cross reference prompt. * tool calling, other workflows, memory, and context management
Here's an alternative AI version:
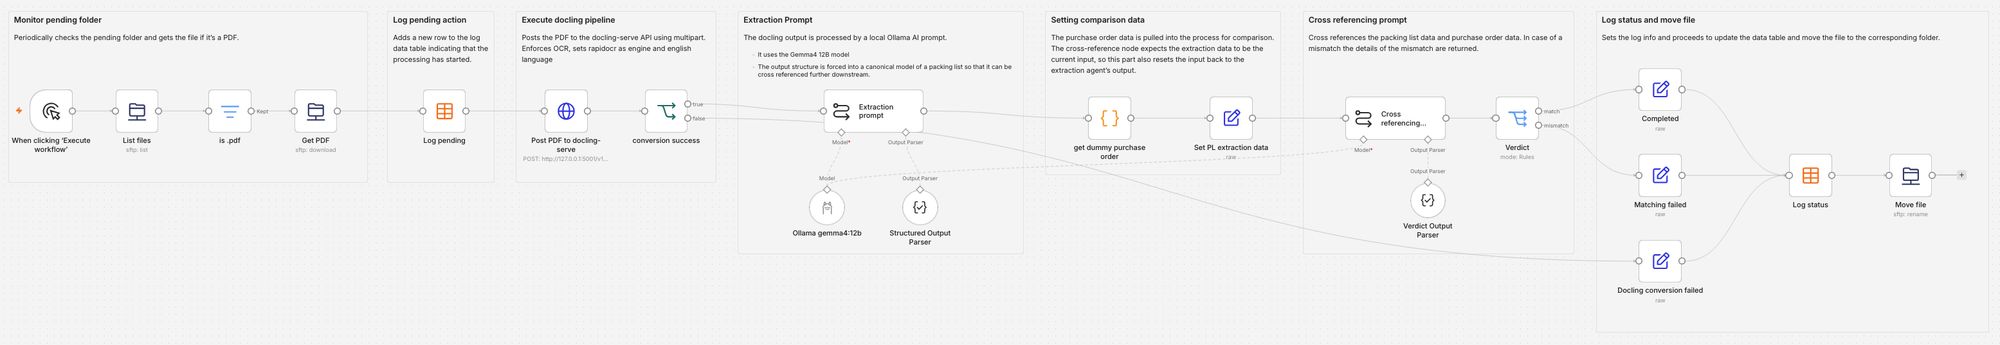
If you want to try it out or check the prompts, you can find an export of this flow in my repo. Look for template-ai-alternative.json. The original version from part 3 was also published as an n8n template that you can find here.
This solution worked 5 times in a row with all the test files without errors. So far so good! We have the same behaviour. However when I looked at the execution time and token usage I read a different story:
| Template | Token cost original | Token cost alternative | Execution time original | Execution time alternative |
|---|---|---|---|---|
| 1 page PL ACME | ~1046 | ~5127 | 45.096s | 1m 29.667s |
| 2 page PL ACME | ~1226 | ~5864 | 1m 3.112s | 1m 49.111s |
| 2 page PL ACME (w. errors) | ~1218 | ~8043 | 51.816s | 2m 32.044s |
| 2 page PL Stark (w. sku healing) | ~2299 | ~12754 | 1m 19.725s | 4m 6.109s |
Using Mac M1, Ollama with gemma4:12b-mlx
Letting an LLM do everything increases the token costs about 5 times and multiplies the execution time by 2 for the clean packing lists. This gap gets wider for the messier cases where we need an LLM to help. The file with input errors burns almost 7 times the tokens and the Stark file with SKU healing triples the time.
The token cost is locally less visible in money than using a provider with a per token model. But it's no secret that AI uses a lot of power so I feel we should use it wisely. Adding more AI in this case also means adding more time to the process. It also trades in a deterministic step for a non deterministic one. LLMs can occasionally return a different answer on identical input which makes me feel a bit uncomfortable...
Having said that, the LLM could be a lot more capable of handling edge cases and innocent input errors. This could in turn reduce the maintenance burden of a script. Another option is to keep the script but have AI maintain it, which is cheaper at runtime since you're not burning extra tokens on every workflow execution. I'd rather spend an hour of AI assisted development on maintaining the solution than spending 5× the tokens on every execution forever.
So, was my solution in n8n too rigid?
For this use case I'd keep the hybrid approach that uses the script to deterministically match most cases and calls on AI to help resolve the edge cases. The tokens I save per execution give me a good budget to spend on maintaining it and keeping it faster.
That's it for now! As always, if you have any thoughts or feedback about the ideas in this post then I'm happy to hear from you!